
Stable Diffusion v1.1: the original release, used creatively
Fast Facts:
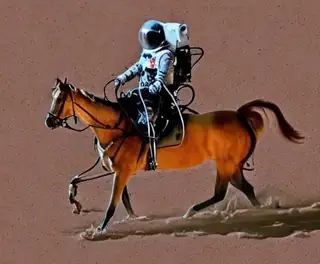
Stable Diffusion v1.1 from CompVis is the earliest released checkpoint of the series, trained first at 256x256 on LAION-2B and then at 512x512 on high-resolution LAION images. It is in the catalog as a piece of history and because its looseness is useful.
Expect soft forms, strange hands and heavy blur on people. Expect also beautiful abstract textures, painterly landscapes and a distinct 2022 look that newer models cannot fake.
Reference
Name | Type | What it is |
|---|---|---|
Prompt | text | Short, evocative phrases. Long prompts are mostly ignored. |
text | Minimal effect; a few words at most. | |
7-10 | Higher values force structure out of the noise. | |
Steps | 30-50 | It needs more steps than later models to settle. |
Resolution | 512x512 | Stay square and small. |
Step by step
- Write a single evocative line: a coral cathedral under green light.
- Generate a batch of eight; variety between seeds is high.
- Optionally run the result through a newer model at 0.3-0.4 denoise to tidy forms while keeping the composition.
Examples
Abstract texture
a cathedral made of coral and bioluminescent algae, deep sea, green light, oil painting
Early-AI aesthetic
dreamlike photograph of a forgotten ballroom filling with fog, 2022 ai art style
Creative idea: album cover
album cover, a melting brass trumpet on a salt flat at dusk, grainy, surreal, cyanotype
Tips
- Avoid faces unless you want the early-AI uncanny look on purpose.
- Use it as a composition generator and refine in another model.
- Film and print words (cyanotype, daguerreotype) suit its softness.
Troubleshooting
Everything is blurry
Why it happens
This is the model's nature.
How to fix it
Prompt ignored
Why it happens
Weak text understanding.
How to fix it
Shorten the prompt to the two or three most important nouns and raise CFG to 9-10.
Questions
Why is this in the top 100?
Curiosity and history: it is the first public Stable Diffusion checkpoint.
Do SD 1.5 LoRAs work?
They load, but were trained against 1.5 weights and behave unpredictably here.
Links and sources
Models in this guide
Written by
Runs this ship. Has opinions about VAE decode times that nobody asked for. Believes weights want to be free and that any model you cannot download is a subscription with extra steps. Will not be taking questions about the 400 GB of checkpoints on the NAS.
All guides by Captain
Related guides
DreamShaper 8 Inpainting: fixing and changing parts of an image
Oct 1, 2026
Realistic Vision 5.1 Inpainting: photoreal repairs and edits
Oct 2, 2026
Ghibli Diffusion: the ghibli style token and how to use it
Sep 30, 2026

Waifu Diffusion: Danbooru-tag prompting for a classic anime model
Oct 1, 2026
More guides

Stable Diffusion 1.5: the classic model, prompted properly
Oct 2, 2026

How generative AI image models work: diffusion, latents and text encoders explained simply
Aug 28, 2025

What is a LoRA and how to use one in ComfyUI, Forge, Automatic1111 and on the cloud
May 20, 2026

Flux vs SDXL vs SD 1.5 vs Qwen vs Z-Image: which model family to use in 2026
May 22, 2026
Automatic1111 (Stable Diffusion WebUI) errors and fixes
May 14, 2026