- #1
- #2

flux2
FLUX.2 [dev] is Black Forest Labs' second-generation open-weights image model, released in November 2025. It is a much larger flow-matching transformer than FLUX.1 that uses the Mistral Small 3.1 vision-language model as its text encoder,…FLUX.2 [dev] is Black Forest Labs' second-generation open-weights image model, released in November 2025. It is a much larger flow-matching transformer than FLUX.1 that uses the Mistral Small 3.1 vision-language model as its text encoder, which gives it far better understanding of long, descriptive prompts, reliable multi-line typography and real-world knowledge about brands, materials and lighting. It was designed from the start as a unified model: the same weights generate from text, edit an existing picture from instructions, and combine up to ten reference images for character, product or style consistency, with output up to 4 megapixels. The family also includes the smaller FLUX.2 Klein 4B and 9B distillations that most Flux2 LoRAs in this catalog are trained on. This entry is the text-to-image workflow, accelerated with a turbo LoRA so that it finishes in a handful of steps.
- #3
flux
The fastest Flux DEV fp8 workflow, supports up to 5 loras. Built-in upscaler is a factor of 1.4, modify with /slot8 - #4

qwen
Qwen-Image is the image generation foundation model of Alibaba's Qwen team, released as open weights in August 2025. It is a 20-billion-parameter multimodal diffusion transformer that reads prompts through the Qwen2.5-VL vision-language…Qwen-Image is the image generation foundation model of Alibaba's Qwen team, released as open weights in August 2025. It is a 20-billion-parameter multimodal diffusion transformer that reads prompts through the Qwen2.5-VL vision-language model, and its headline strength is text: it renders long paragraphs, multi-line signs, posters and mixed Chinese and English typography with an accuracy no earlier open model reached. The same team's technical report also shows strong results for layout-heavy prompts, infographics and precise image editing, and the companion Qwen-Image-Edit model is the basis of many editing workflows. It generates natively around 1.3 to 1.6 megapixels in the usual aspect ratios and takes natural-language prompts rather than tag lists; the team recommends appending quality phrases such as 'Ultra HD, 4K, cinematic composition'. This entry is the version 2512 text-to-image workflow (the December 2025 refresh of the weights); the original release is kept as qwen-v1.
- #5
sdxl
Stable Diffusion XL version 1.0 is here, and the Refiner 1.0 is also installed. This is the official full release, but our software needs adjustment to fully support it. Only the /render command works and SDXL cannot be mixed with old…Stable Diffusion XL version 1.0 is here, and the Refiner 1.0 is also installed. This is the official full release, but our software needs adjustment to fully support it. Only the /render command works and SDXL cannot be mixed with old styles, recipes, loras, inversions, and other commands yet. Keep an eye on the XL news topic in Telegram VIP for more information
- #6

DeepSeek V4.1 Flash
DeepSeek | 1,048,576 token context | $0.04/M input, $0.68/M output. DeepSeek V4.1 Flash is a sparse mixture-of-experts model from DeepSeek, and the first built on the company's Causal Encoder-Decoder (CED) architecture. It activates 8B…DeepSeek | 1,048,576 token context | $0.04/M input, $0.68/M output. DeepSeek V4.1 Flash is a sparse mixture-of-experts model from DeepSeek, and the first built on the company's Causal Encoder-Decoder (CED) architecture. It activates 8B parameters on input and 16B on output from a 552B-parameter backbone, an asymmetric split that keeps per-token compute low relative to the model's total size. Image understanding is native to the architecture, with visual and text embeddings trained jointly from the start of pre-training rather than added afterward as in the earlier experimental V4 Flash Vision ExpOpens in new tab. It is suited for coding, terminal, and computer-use agents, along with long-horizon tasks that must run to completion across many steps and long-context analysis. Compressed KV caching cuts cache memory to roughly a quarter of the previous Flash generation, significantly reducing costs on agentic workloads. DeepSeek positions it as the cost-efficient tier of the V4.1 family and reports that it exceeds V4 ProOpens in new tab on performance, speed, and task completion time.
- #7

sdv15
Stable Diffusion 1.5 by Stability / RunwayML, the OG model. Someone said it was weird that we didn't have this in the concepts collection, and they were correct, so here you go! Of course, this model is over a year old, but it's still…Stable Diffusion 1.5 by Stability / RunwayML, the OG model. Someone said it was weird that we didn't have this in the concepts collection, and they were correct, so here you go! Of course, this model is over a year old, but it's still fantastic in its own right.
- #8
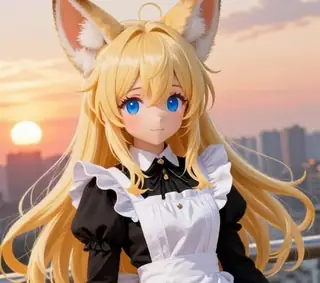
zimage turbo
Also known as "ZIT" -- Z-Image Turbo from Alibaba is a fast, low-steps general purpose realism text to image model. Doesn't support negative prompts. Works best at around 9 steps and 1 guidance at 1024x1024. - #9
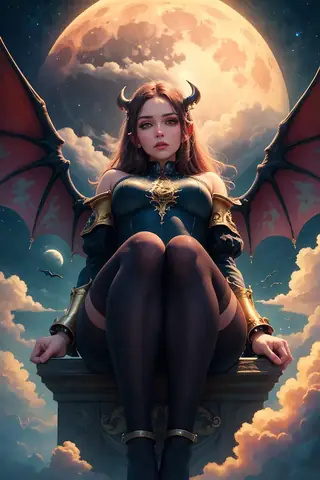
ReV Animated
Rev Animated 2.0 is under new management - the project is now maintained by Zovya This is a remaster of the classic popular Revani series for SD15 - #10
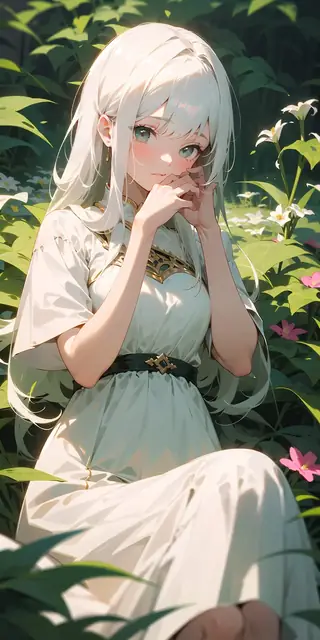
Counterfeit V3.0
CounterfeitV3.0 by rqdwdw. The 3.0 version of Counterfeit has much brighter colors and more focus on the subject, whereas the previous model was more muted and pastel-like. The backgrounds look totally different in particular, so we're…CounterfeitV3.0 by rqdwdw. The 3.0 version of Counterfeit has much brighter colors and more focus on the subject, whereas the previous model was more muted and pastel-like. The backgrounds look totally different in particular, so we're going to keep both. It should be noted that there are 10 upvotes and 3 comments about green spots from users on Civitai.
- #11
Wan 2.1
Wan 2.1 is the February 2025 generation of Alibaba's open Wan video models: 1.3B and 14B weights for text-to-video and image-to-video. It has been superseded by Wan 2.2 (July 2025), which gives clearly better motion, detail and prompt…Wan 2.1 is the February 2025 generation of Alibaba's open Wan video models: 1.3B and 14B weights for text-to-video and image-to-video. It has been superseded by Wan 2.2 (July 2025), which gives clearly better motion, detail and prompt following with the same kind of workflows, so there is no reason to start with Wan 2.1 in 2026 or later. This page stays as a reference for the older LoRAs and workflows that were made for it.
- #12
GLM 5.3 Flash
Z.ai | 1,048,576 token context | $0.02/M input, $0.72/M output. GLM-5.3-Flash is a native multimodal model from Z.ai. It is suited for efficient coding and long-horizon agent tasks. Its hybrid sparse and linear attention architecture…Z.ai | 1,048,576 token context | $0.02/M input, $0.72/M output. GLM-5.3-Flash is a native multimodal model from Z.ai. It is suited for efficient coding and long-horizon agent tasks. Its hybrid sparse and linear attention architecture maintains accurate long-context behavior while reducing compute overhead. Yes, the stealth model Ox Alpha was revealed to be ZAI's new model, GLM-5.3 Flash.
- #13
Hy4 preview
Tencent | 1,048,576 token context | $0.83/M input, $2.50/M output. Tencent: Hy4 preview is a mixture-of-experts model from Tencent, with 49B active parameters out of 770B total. It is designed for coding agents, complex tool-use workflows,…Tencent | 1,048,576 token context | $0.83/M input, $2.50/M output. Tencent: Hy4 preview is a mixture-of-experts model from Tencent, with 49B active parameters out of 770B total. It is designed for coding agents, complex tool-use workflows, and productivity tasks that require planning, context continuity, and sustained multi-step execution.
- #14
MiMo V2.6 Flash
Xiaomi | ngữ cảnh 1.050.000 token | $0.14/M đầu vào, $0.28/M đầu ra. MiMo-V2.6-Flash là một mô hình nền tảng mã nguồn mở do Xiaomi phát triển. Xây dựng trên kiến trúc Mixture-of-Experts với tổng số 309 tỷ tham số và 15 tỷ tham số kích hoạt…Xiaomi | ngữ cảnh 1.050.000 token | $0.14/M đầu vào, $0.28/M đầu ra. MiMo-V2.6-Flash là một mô hình nền tảng mã nguồn mở do Xiaomi phát triển. Xây dựng trên kiến trúc Mixture-of-Experts với tổng số 309 tỷ tham số và 15 tỷ tham số kích hoạt mỗi token, nó sử dụng cơ chế chú ý kết hợp để tăng hiệu quả tính toán. Mô hình có cửa sổ ngữ cảnh 1 triệu token và khả năng đa phương thức gốc. Tối ưu cho các quy trình agentic, nó mang lại hiệu suất mạnh mẽ trong các kịch bản lập trình, hình ảnh, tổng quát và nghiên cứu, xuất sắc trong các nhiệm vụ phức tạp, dài hạn với khả năng tổng quát hóa vững chắc trên nhiều dạng agent khác nhau.
- #15
DeepSeek V4 Flash 0731
DeepSeek | 1,048,576 token context | $0.01/M input, $1.28/M output. DeepSeek V4 Flash 0731 is a sparse mixture-of-experts model from DeepSeek, with 13B active parameters out of 284B total. This re-post-trained revision is suited for…DeepSeek | 1,048,576 token context | $0.01/M input, $1.28/M output. DeepSeek V4 Flash 0731 is a sparse mixture-of-experts model from DeepSeek, with 13B active parameters out of 284B total. This re-post-trained revision is suited for coding, reasoning, and agent workflows. This is the GA release of DeepSeek V4 Flash.
- #16
- #17

- #18
Nemotron 3 Ultra
NVIDIA | ngữ cảnh 262.144 token | $0.60/M đầu vào, $2.40/M đầu ra. NVIDIA Nemotron 3 Ultra là một mô hình tiên phong về suy luận và điều phối từ NVIDIA, với 55 tỷ tham số kích hoạt trên tổng số 550 tỷ tham số (MoE). Xây dựng trên kiến trúc…NVIDIA | ngữ cảnh 262.144 token | $0.60/M đầu vào, $2.40/M đầu ra. NVIDIA Nemotron 3 Ultra là một mô hình tiên phong về suy luận và điều phối từ NVIDIA, với 55 tỷ tham số kích hoạt trên tổng số 550 tỷ tham số (MoE). Xây dựng trên kiến trúc hỗn hợp Transformer-Mamba mixture-of-experts, nó hỗ trợ đầu vào và đầu ra văn bản với cửa sổ ngữ cảnh lên đến 1 triệu token. Mô hình phù hợp cho các quy trình agentic chạy dài, bao gồm điều phối agent, agent lập trình, nghiên cứu sâu và các nhiệm vụ doanh nghiệp phức tạp. Nó đặc biệt mạnh về suy luận và lập kế hoạch nhiều bước, với khả năng suy luận thông lượng cao thiết kế cho các pipeline agent khối lượng lớn. Đây là một phần của dòng mô hình mở NVIDIA Nemotron dành cho AI agentic.
- #19
Step 5 Preview
StepFun | 1,048,576 token context | $1.00/M input, $2.70/M output. Step 5 Preview is StepFun's flagship model for agentic work, built on a sparse Mixture-of-Experts architecture (27B active / 600B total parameters). It performs strongly in…StepFun | 1,048,576 token context | $1.00/M input, $2.70/M output. Step 5 Preview is StepFun's flagship model for agentic work, built on a sparse Mixture-of-Experts architecture (27B active / 600B total parameters). It performs strongly in software engineering and professional knowledge work, with particular strength in finance. It is designed for extended tasks that span large codebases and documents, using tools and refining results over multiple steps.
- #20

Add More Details Detail Enhancer / Tweaker (细节调整) LoRA
Add More Details - Detail Enhancer / Tweaker (细节调整) LoRA by Lykon writes: his between 0.5 and 1 weight, depending on your preference. You can go lower than 0.5 for a more subtle effect, of course. I also found out that this gives some…Add More Details - Detail Enhancer / Tweaker (细节调整) LoRA by Lykon writes: his between 0.5 and 1 weight, depending on your preference. You can go lower than 0.5 for a more subtle effect, of course. I also found out that this gives some interesting results at negative weight, sometimes
- #21

waifu
waifu-diffusion by hakurei. A long running base model trained on crisp-looking anime. Compared to your other anime base model options, this one is fairly well-rounded, which unfortunately has been detrimental in making it a clear winner in…waifu-diffusion by hakurei. A long running base model trained on crisp-looking anime. Compared to your other anime base model options, this one is fairly well-rounded, which unfortunately has been detrimental in making it a clear winner in any category.
- #22
hyper
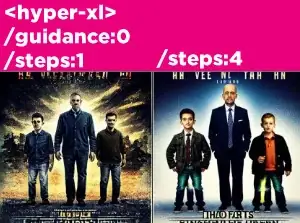
The "hyper-xl" model is optimized to significantly increase generation speed. - #23
GLM 5.3
Z.ai | ngữ cảnh 1.048.576 token | $0.08/M đầu vào, $4.80/M đầu ra. GLM-5.3 là mô hình suy luận quy mô lớn từ Z.ai, xây dựng cho kỹ thuật phần mềm phức tạp và các tác vụ agent dài hạn. Nó hỗ trợ đầu vào và đầu ra văn bản với cửa sổ ngữ cảnh…Z.ai | ngữ cảnh 1.048.576 token | $0.08/M đầu vào, $4.80/M đầu ra. GLM-5.3 là mô hình suy luận quy mô lớn từ Z.ai, xây dựng cho kỹ thuật phần mềm phức tạp và các tác vụ agent dài hạn. Nó hỗ trợ đầu vào và đầu ra văn bản với cửa sổ ngữ cảnh 1 triệu token, và cải tiến so với GLM-5.2 về lập trình và cân bằng giữa hiệu suất và hiệu quả token. Suy luận luôn bật và không thể tắt. Hỗ trợ các mức nỗ lực suy luận thấp, cao và tối đa; tối đa là mặc định.
- #24
- #25
Detail Tweaker LoRA (细节调整LoRA)
LoRA designed for removing or adding detail while keeping the style of the render the same. Current strength is good from 0 - 2 depending on your use case. In the future, it can be used as negative weight to reduce details. Works with…LoRA designed for removing or adding detail while keeping the style of the render the same. Current strength is good from 0 - 2 depending on your use case. In the future, it can be used as negative weight to reduce details. Works with anime, semi-real and realistic models and styles.
- #26
DeepSeek V4 Flash 0423
DeepSeek | ngữ cảnh 1.048.576 token | $0.09/M đầu vào, $0.18/M đầu ra. DeepSeek V4 Flash là một mô hình Mixture-of-Experts tối ưu hiệu quả từ DeepSeek với tổng số 284 tỷ tham số và 13 tỷ tham số kích hoạt, hỗ trợ cửa sổ ngữ cảnh 1 triệu…DeepSeek | ngữ cảnh 1.048.576 token | $0.09/M đầu vào, $0.18/M đầu ra. DeepSeek V4 Flash là một mô hình Mixture-of-Experts tối ưu hiệu quả từ DeepSeek với tổng số 284 tỷ tham số và 13 tỷ tham số kích hoạt, hỗ trợ cửa sổ ngữ cảnh 1 triệu token. Nó được thiết kế cho suy luận nhanh và các khối lượng công việc thông lượng cao, đồng thời duy trì hiệu suất suy luận và lập trình mạnh mẽ. Mô hình bao gồm chú ý kết hợp để xử lý ngữ cảnh dài hiệu quả. Hỗ trợ các mức nỗ lực suy luận cao và xhigh; xhigh tương ứng với suy luận tối đa. Nó phù hợp cho các ứng dụng như trợ lý lập trình, hệ thống chat và quy trình agent nơi độ phản hồi và hiệu quả chi phí quan trọng.
- #27
Hy3
Tencent | 262,144 token context | $0.13/M input, $0.53/M output. Hy3 is a 295B-parameter Mixture-of-Experts model from Tencent (21B active, 192 experts with top-8 routing) built for reasoning, agentic workflows, and real-world production…Tencent | 262,144 token context | $0.13/M input, $0.53/M output. Hy3 is a 295B-parameter Mixture-of-Experts model from Tencent (21B active, 192 experts with top-8 routing) built for reasoning, agentic workflows, and real-world production use. It supports a configurable reasoning effort: a direct no-think mode by default, plus low and high chain-of-thought modes for complex math, coding, and multi-step problems. With a 256K context window, Hy3 targets long-horizon tasks, including improved coreference resolution, multi-turn constraint tracking, and stable tool-calling that generalizes across agent scaffoldings. Tencent positions it as a reliable, cost-effective option across coding, document processing, financial analysis, game development, and frontend design, with a strong emphasis on grounded, anti-hallucination behavior that answers when grounded and flags when evidence is missing rather than fabricating.
- #28
ebara_pony
Ebara Pony V3 by Shareman writes: positive: masterpiece, best quality, score_9, score_8_up, score_7_up,source_anime, - #29
- #30
Kimi K3
MoonshotAI | 1,048,576 token context | $0.30/M input, $11.94/M output. Kimi K3 is a 2.8T parameter open-weight multimodal reasoning model from Moonshot AI. It is suited for complex coding, knowledge work, and long-horizon agentic…MoonshotAI | 1,048,576 token context | $0.30/M input, $11.94/M output. Kimi K3 is a 2.8T parameter open-weight multimodal reasoning model from Moonshot AI. It is suited for complex coding, knowledge work, and long-horizon agentic workflows, and is particularly strong at navigating large repositories, using tools, debugging, and iterating against images, logs, tests, and runtime feedback. Its architecture uses KDA and Attention Residuals for computational efficiency.
- #31
MiMo V2.5
Xiaomi | ngữ cảnh 1.050.000 token | $0.14/M đầu vào, $0.28/M đầu ra. MiMo-V2.5 là mô hình omnimodal gốc của Xiaomi. Nó mang lại hiệu suất agentic cấp Pro với chi phí suy luận khoảng một nửa, đồng thời vượt trội hơn MiMo-V2-Omni trong nhận…Xiaomi | ngữ cảnh 1.050.000 token | $0.14/M đầu vào, $0.28/M đầu ra. MiMo-V2.5 là mô hình omnimodal gốc của Xiaomi. Nó mang lại hiệu suất agentic cấp Pro với chi phí suy luận khoảng một nửa, đồng thời vượt trội hơn MiMo-V2-Omni trong nhận thức đa phương thức qua các tác vụ hiểu hình ảnh và video. Cửa sổ ngữ cảnh 1 triệu token hỗ trợ tài liệu hoàn chỉnh, hội thoại kéo dài và bối cảnh tác vụ phức tạp trong một lần xử lý, làm cho nó lý tưởng để tích hợp với các framework agent nơi suy luận mạnh mẽ, nhận thức phong phú và hiệu quả chi phí đều quan trọng.
- #32
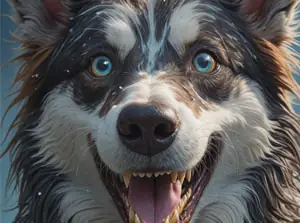
extremely detailed (no trigger) sliders.ntcai.xyz
Extremely detailed - sliders / ntcai.xyz by ntc. Make everything extremely detailed or bland (negative). Examples at 4-5 strength Trained for 6000 instances with sliders - #33
GLM 5.2
Z.ai | 1,048,576 token context | $0.04/M input, $9.00/M output. GLM 5.2 is a large-scale reasoning model from Z.ai. It supports text input and output with a 1M-token context window, and is suited for long-horizon agent workflows,…Z.ai | 1,048,576 token context | $0.04/M input, $9.00/M output. GLM 5.2 is a large-scale reasoning model from Z.ai. It supports text input and output with a 1M-token context window, and is suited for long-horizon agent workflows, project-level software engineering, and complex multi-step automation. Reasoning efforts high and xhigh are supported; xhigh maps to max reasoning. It is particularly strong at coding and tool use across long-running tasks, able to maintain engineering context and follow standards consistently through a full development workflow, from requirements to multi-platform deployment, in a single task.
- #34
MiniMax M3
MiniMax | ngữ cảnh 1.048.576 token | $0.30/M đầu vào, $1.20/M đầu ra. MiniMax-M3 là mô hình nền tảng đa phương thức từ MiniMax. Nó hỗ trợ đầu vào văn bản, hình ảnh và video với đầu ra văn bản, cửa sổ ngữ cảnh 1 triệu token, và phù hợp cho…MiniMax | ngữ cảnh 1.048.576 token | $0.30/M đầu vào, $1.20/M đầu ra. MiniMax-M3 là mô hình nền tảng đa phương thức từ MiniMax. Nó hỗ trợ đầu vào văn bản, hình ảnh và video với đầu ra văn bản, cửa sổ ngữ cảnh 1 triệu token, và phù hợp cho công việc agentic dài hạn, lập trình và sử dụng công cụ. Nó xây dựng trên MiniMax Sparse Attention (MSA), thay thế chú ý đầy đủ bằng lựa chọn khối KV để giảm chi phí tính toán trên mỗi token ở ngữ cảnh dài — khoảng 1/20 chi phí thế hệ trước ở 1 triệu token, với tốc độ tiền xử lý và giải mã nhanh hơn đáng kể trong khi giữ chất lượng trên hầu hết các tác vụ. Được huấn luyện như mô hình đa phương thức gốc trên dữ liệu xen kẽ và tinh chỉnh cho hợp tác đa lượt, giống môi trường sản xuất qua framework mô phỏng người dùng tương tác, mô hình hướng đến các nhiệm vụ kéo dài, đa bước thay vì thực thi một lượt.
- #35
[KREA 2] Detail Slider
by alcaitiff - [KREA 2] Detail Slider - #36
MiMo V2.6 Pro
Xiaomi | ngữ cảnh 1,050,000 token | $0.43/M đầu vào, $0.87/M đầu ra. MiMo-V2.6-Pro là mô hình nền tảng hàng đầu do Xiaomi phát triển. Được xây dựng với quy mô hơn 1T tham số, nó được thiết kế để nâng cao giới hạn khả năng cho các khối…Xiaomi | ngữ cảnh 1,050,000 token | $0.43/M đầu vào, $0.87/M đầu ra. MiMo-V2.6-Pro là mô hình nền tảng hàng đầu do Xiaomi phát triển. Được xây dựng với quy mô hơn 1T tham số, nó được thiết kế để nâng cao giới hạn khả năng cho các khối lượng công việc đòi hỏi cao nhất. Mô hình có cửa sổ ngữ cảnh 1M token và khả năng đa phương thức nguyên bản. Tối ưu cho các quy trình làm việc tác nhân, nó mang lại hiệu suất hàng đầu trong các kịch bản lập trình, hình ảnh, tổng quát và nghiên cứu, xuất sắc trong các nhiệm vụ phức tạp, dài hạn với khả năng tổng quát hóa mạnh mẽ trên nhiều loại tác nhân khác nhau.
- #37
- #38
DeepSeek V4 Pro 0813
DeepSeek | 1,048,576 token context | $1.32/M input, $3.96/M output. DeepSeek V4 Pro 0813 is a large-scale mixture-of-experts model from DeepSeek. This is the GA release of DeepSeek V4 Pro. - #39
Laguna S 2.1
Poolside | ngữ cảnh 1.048.576 token | $0.09/M đầu vào, $0.18/M đầu ra. Laguna S 2.1 là mô hình agent lập trình mới nhất từ PoolsideOpens in new tab. Laguna S 2.1 là mô hình 118 tỷ tham số tổng với 8 tỷ tham số kích hoạt, đạt điểm 70.2%…Poolside | ngữ cảnh 1.048.576 token | $0.09/M đầu vào, $0.18/M đầu ra. Laguna S 2.1 là mô hình agent lập trình mới nhất từ PoolsideOpens in new tab. Laguna S 2.1 là mô hình 118 tỷ tham số tổng với 8 tỷ tham số kích hoạt, đạt điểm 70.2% trên Terminal-Bench 2.1 và 40.4% trên DeepSWE, trở thành một trong những mô hình lập trình mạnh nhất trong phân khúc của nó. Trọng số mở theo giấy phép OpenMDW-1.1. Laguna S 2.1 được thiết kế cho các trường hợp sử dụng kỹ thuật phần mềm và lập trình agentic, và bạn chịu trách nhiệm xác nhận nó phù hợp với ứng dụng dự định của bạn. Laguna S 2.1 tuân theo Giấy phép OpenMDW-1.1Opens in new tab và nên được sử dụng phù hợp với Chính sách Sử dụng Chấp nhận được của PoolsideOpens in new tab. Chúng tôi khuyên không nên vượt qua các biện pháp an toàn của Laguna S 2.1 mà không thực hiện các biện pháp giảm thiểu tương đương phù hợp với trường hợp sử dụng của bạn. Vui lòng báo cáo các lỗ hổng bảo mật hoặc mối quan ngại về an toàn tới [email protected]. Nếu bạn sử dụng Laguna S 2.1 miễn phí, chúng tôi có thể sử dụng đầu vào và đầu ra của bạn để huấn luyện và cải thiện mô hình.
- #40
lyh_anime_Flux
Flux.1 D checkpoint, hosted on Yodayo with 23,546 generation runs there. The model is also listed on Civitai. - #41

Background Detail Enhancer
Background Detail Enhancer by ZyloO - #42
- #43
Nemotron 3.5 Lightning
NVIDIA | ngữ cảnh 262,144 token | $0.07/M đầu vào, $0.20/M đầu ra. NVIDIA Nemotron 3.5 Lightning là mô hình hỗn hợp chuyên gia mở từ NVIDIA, với 3B tham số kích hoạt trong tổng số 30B tham số. Nó phù hợp cho các khối lượng công việc tác…NVIDIA | ngữ cảnh 262,144 token | $0.07/M đầu vào, $0.20/M đầu ra. NVIDIA Nemotron 3.5 Lightning là mô hình hỗn hợp chuyên gia mở từ NVIDIA, với 3B tham số kích hoạt trong tổng số 30B tham số. Nó phù hợp cho các khối lượng công việc tác nhân có thông lượng cao và các nhiệm vụ chuyên biệt được hưởng lợi từ tùy chỉnh theo lĩnh vực.
- #44
playground2
This is the 1024 Aesthetic version of the general purpose Playground 2 concept, a rebuild of SDXL. Try it as a second opinion when you don't like what gives you. It can handle realism as well as paintings and ilustrations - #45
DeepSeek V4 Pro 0423
DeepSeek | 1,048,576 token context | $0.96/M input, $1.91/M output. DeepSeek V4 Pro is a large-scale Mixture-of-Experts model from DeepSeek with 1.6T total parameters and 49B activated parameters, supporting a 1M-token context window. It…DeepSeek | 1,048,576 token context | $0.96/M input, $1.91/M output. DeepSeek V4 Pro is a large-scale Mixture-of-Experts model from DeepSeek with 1.6T total parameters and 49B activated parameters, supporting a 1M-token context window. It is designed for advanced reasoning, coding, and long-horizon agent workflows, with strong performance across knowledge, math, and software engineering benchmarks. Built on the same architecture as DeepSeek V4 Flash, it introduces a hybrid attention system for efficient long-context processing. Reasoning efforts high and xhigh are supported; xhigh maps to max reasoning. It is well suited for complex workloads such as full-codebase analysis, multi-step automation, and large-scale information synthesis, where both capability and efficiency are critical
- #46
Chroma
Chroma checkpoint, hosted on Yodayo with 36,370 generation runs there. The model is also listed on Civitai. - #47
gpt oss 120b
OpenAI | ngữ cảnh 131,072 token | $0.15/M đầu vào, $0.60/M đầu ra. gpt-oss-120b là mô hình ngôn ngữ Mixture-of-Experts (MoE) 117B tham số trọng số mở từ OpenAI, được thiết kế cho các trường hợp sử dụng sản xuất đòi hỏi suy luận cao, tác…OpenAI | ngữ cảnh 131,072 token | $0.15/M đầu vào, $0.60/M đầu ra. gpt-oss-120b là mô hình ngôn ngữ Mixture-of-Experts (MoE) 117B tham số trọng số mở từ OpenAI, được thiết kế cho các trường hợp sử dụng sản xuất đòi hỏi suy luận cao, tác nhân và đa mục đích. Nó kích hoạt 5.1B tham số mỗi lần chạy và được tối ưu để chạy trên một GPU H100 với lượng tử hóa MXFP4 nguyên bản. Mô hình hỗ trợ độ sâu suy luận có thể cấu hình, truy cập chuỗi suy nghĩ đầy đủ và sử dụng công cụ nguyên bản, bao gồm gọi hàm, duyệt web và tạo đầu ra có cấu trúc.
- #48
level4
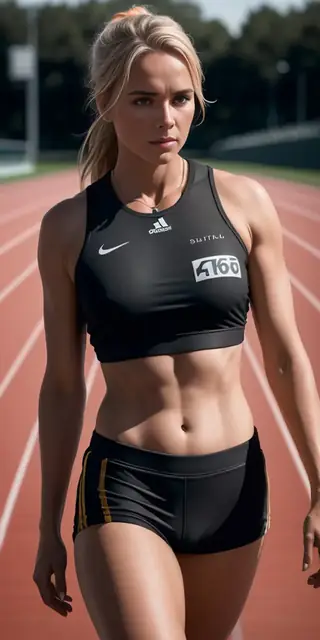
Level4 by AreThoseLevel4Plates is the creator of and this one, made popular for its stunning photos of athletes. Level4 is great for beginners, because it responds well to simple prompts, but to get a realistic photo out of it may take…Level4 by AreThoseLevel4Plates is the creator of and this one, made popular for its stunning photos of athletes. Level4 is great for beginners, because it responds well to simple prompts, but to get a realistic photo out of it may take more work, and there are better options. As a semi-realistic general model it's efforlessly great for portraits, cars, landscapes. The creator demos it as the go-to model for creating female athletes. Try the #nfix recipe with it or #cinematic
- #49
Realism Enhancer Krea2
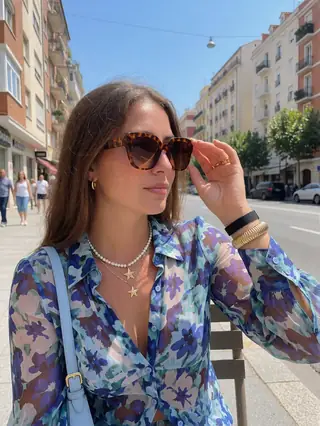
by HearmemanAI - Realism Enhancer Krea2 - #50
Độ nóng là điểm xu hướng nội bộ của chúng tôi, từ lạnh đến 9999°. Nó thay đổi mỗi ngày theo tín hiệu sử dụng và mức độ phổ biến từ các cộng đồng và dịch vụ xung quanh từng mô hình. Bảng xếp hạng bao gồm mô hình gốc, LoRA, embedding và mô hình văn bản của mọi họ trong danh mục.
Duyệt theo họ mô hình